AI Engineering · Classification and Evaluation
Ticket Triage
Support Classification
A support ticket classifier that starts with rule-based routing, integrates a real AI model, measures accuracy on labeled examples, and keeps a clear line between custom Python code and the API boundary.
Status: Shipped
A Python classifier covering JSON parsing, Pydantic validation, rule-based classification, OpenAI API integration, and evaluation metrics. Includes a test suite and a full reference implementation.
The problem
Support teams face inconsistent ticket routing:
- •Tickets arrive without a category, slowing triage
- •Manual classification is slow; automation needs to be reliable
- •It's unclear when to use simple rules versus when to call an expensive API
- •How do you measure whether your classifier actually works?
How it works
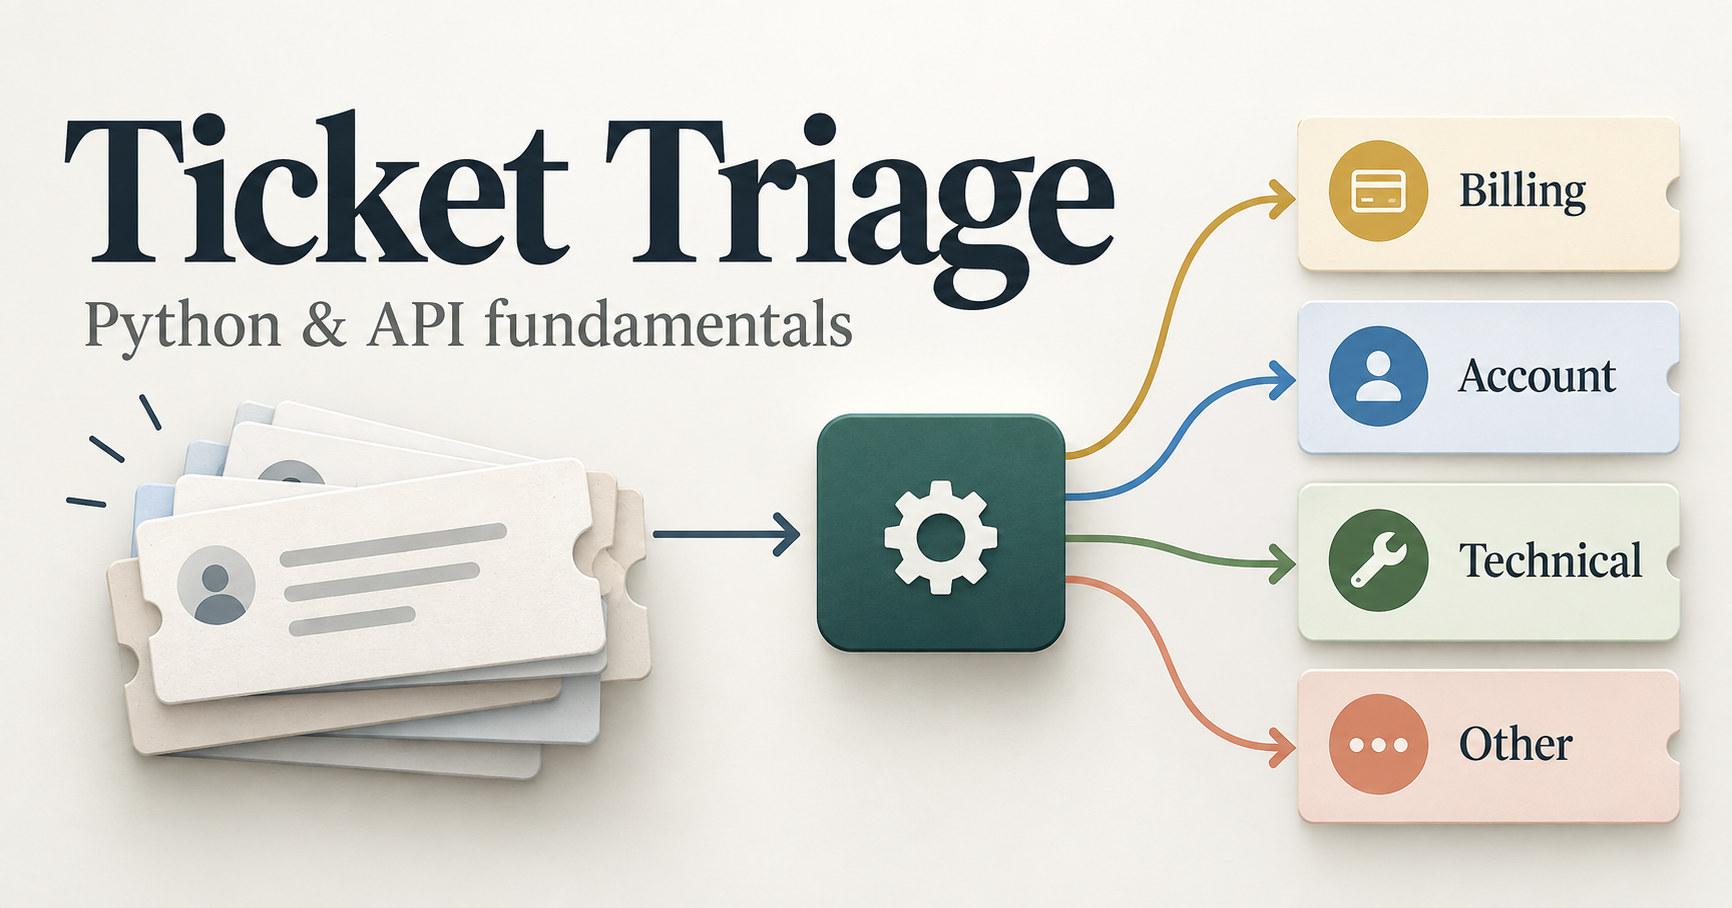
Read a ticket from JSON. Validate its structure with Pydantic. Route it through one of two classifiers: a rule-based keyword matcher that's fast and free, or an OpenAI API call that's accurate and costs money. Log the prediction with timing and token usage. Then compare both against human labels to see which approach matches reality better.
What I built
A ten-stage build, from project setup through evaluation and release:
Engineering highlights
The engineering fundamentals behind the classifier:
Python fundamentals
Variables, functions, loops, conditionals, file I/O, and modules.
Data validation
Pydantic schemas enforce structure at boundaries, not just at parse time.
Rules vs. AI
Simple keyword matching compared against a real model on dev and holdout examples.
API integration
Structured requests, response handling, and tracking of token costs and latency.
Evaluation design
Labeled examples, dev/holdout splits, accuracy metrics, error analysis.
Error recovery
Missing files, JSON errors, validation failures, API timeouts, and retries.
Why I built it this way
Many AI demos hide the difference between local logic and an API call. This project keeps that boundary explicit: validate input, build a simple rule-based baseline, then add the model call and measure whether it actually improves results.
The core principle: understanding the real work means defining what success means (evaluation), building something simple that works (rules), knowing when to add complexity (the model call), and measuring whether it helped (accuracy on labeled data).